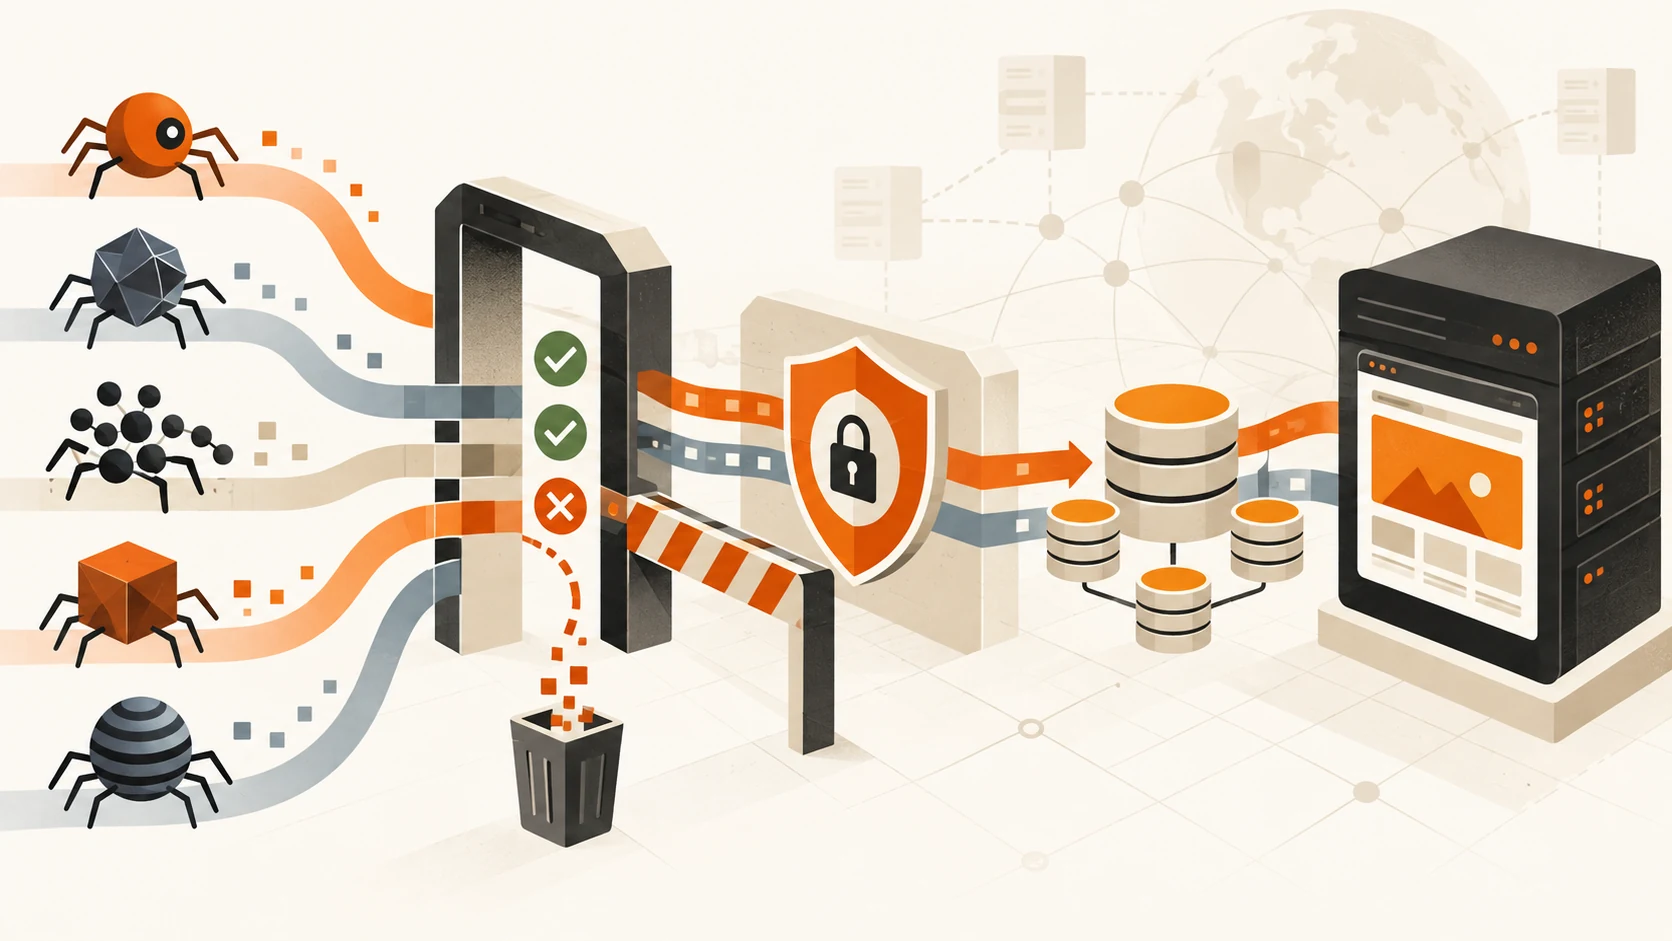
A practical technical SEO process for deciding which AI-related crawlers can reach your site—and proving what happened.
Why “block AI bots” is not a technical strategy
AI-related crawler traffic is not one thing. OpenAI, for example, documents distinct agents for search, training preferences and user-triggered access. A blanket rule can therefore change a training preference, affect search discovery, or interfere with a visit initiated by a real user. Read the current vendor documentation before editing a crawl or firewall rule.
For a business website, the practical question is narrower: which documented requests should be able to fetch public pages, and can the site serve them reliably? The answer belongs with commercial goals, infrastructure capacity and legal policy. It is not a universal SEO checkbox.
Keep Googlebot separate
AI crawler policy does not replace conventional technical SEO. Keep Googlebot, Bingbot, XML sitemaps, canonicals, redirects and indexability healthy first. Google’s documented crawler controls are separate from policies that govern generative-AI training or third-party answer engines.
Three questions before changing robots.txt or a WAF rule
- What job does this crawler perform?
Classify it from the vendor’s current documentation: search/discovery, training preference, or a user-triggered fetch. Record the exact user agent and documentation URL with the decision.
- Can we verify it?
A user-agent header is easy to copy. Use the vendor’s IP/DNS verification guidance or a managed-bot signal from your CDN before allowing a request through a restrictive rule.
- What does the origin cost?
Measure response time, cache status, status code, path and bytes served. WooCommerce checkout, account and search routes may need different protection from a cacheable article or product page.
Build a crawler policy register
Use a small register rather than an unowned collection of copied rules. It keeps commercial, security and technical decisions connected.
| Field | What to record |
|---|---|
| Crawler and purpose | Exact documented user agent, vendor, and whether the job is search, training or user-requested access. |
| Decision | Allow, disallow, monitor, or require verified-bot handling. State the business reason. |
| Scope | Public documentation and articles may be appropriate; private, account, checkout and internal search routes should be protected regardless. |
| Technical control | robots.txt preference, CDN managed-bot setting, WAF rule, cache policy, or an origin limit. Name the owner. |
| Review date | Recheck user agents and vendor verification guidance quarterly or when a vendor changes its crawler documentation. |
A safe implementation order for WordPress and WooCommerce
1. Observe before restricting
Collect a representative period of CDN and origin logs. Segment known verified bots, unknown automated traffic and human traffic. Look for high request rates, repeated cache misses, slow paths, 403/429/5xx responses and repeated requests to obsolete URLs. A list of user agents without logs is not evidence of a capacity problem.
2. Protect expensive and private routes for everyone
Do not build a separate, lighter page version only for crawlers. That creates maintenance risk and can conflict with search quality guidance. Instead, make the normal public response efficient: cache anonymous pages where appropriate, keep pages server-rendered, avoid needless redirect chains, and keep account, cart, checkout, internal search, staging and private endpoints behind the correct controls.
3. Apply controls at the edge
Use your CDN or WAF to challenge, rate-limit or block unverified abusive traffic. Give verified vendor bots the treatment justified by your register. Where capacity is the issue, prefer broad cache improvements and route-specific origin protection over a rule that trusts every request with a familiar header.
4. Keep robots.txt focused
robots.txt for AI-related crawlers is a policy signal, not a load balancer. Use it to express the policy a documented crawler supports; use caching, WAF controls and server limits to enforce resource protection. Test the deployed file on the canonical host and retain a dated copy of every change.
What to measure after a change
- Availability: 200, 403, 429 and 5xx rates by verified bot and route.
- Origin load: cache-hit ratio, response time and PHP/database pressure on uncached paths.
- Discoverability: search-console crawl issues, valid sitemaps and impressions for relevant commercial pages.
- Business outcome: referral traffic, first landing page and enquiry attribution. A crawler change has value only if it supports qualified discovery without damaging reliability.
When to ask for a technical AI SEO review
Ask for a review when Cloudflare or a host has begun challenging legitimate traffic, AI-related referrers appear but landing pages convert poorly, robots.txt has accumulated copied user agents, or WooCommerce pages become slow under automated load. The practical deliverable is a documented policy, verified traffic sample, route-level protection plan and a measurement baseline—not a promise of citations from any platform.
For the commercial and content side, see technical SEO and AI search services. For the site controls themselves, start with the robots.txt guide.
Frequently asked questions
- Can I trust a crawler’s user-agent header?
-
No. Treat it as a clue. Verify requests using the relevant vendor’s published method before exempting them from a restrictive WAF or rate-limit rule.
- Does robots.txt protect server capacity?
-
It communicates a crawler policy where a crawler chooses to respect it. CDN caching, WAF controls and origin protection manage server resources.
- Should every AI-related crawler be allowed?
-
No. Decide per documented purpose, business goal and policy. Allowing a search crawler and allowing a training crawler can be separate choices.
- Will allowing a crawler guarantee an AI citation?
-
No. It only removes one access barrier. Content usefulness, relevance, indexability and each platform’s systems still determine whether a page is surfaced.
AI crawler and technical SEO review
Review crawler policy, cache behaviour, robots.txt, key public templates and the route from AI referral to enquiry.
Evidence-led crawler controls for WordPress and WooCommerce sites.
Discussion
0 comments
No comments yet.
Have a technical question, correction or a different interpretation? Add to the discussion.